

Leveraging QuerySurge for Big Data Testing
We are aware of the current testing challenges in data integration projects, where we have multiple sources and huge volume of data before any transformation or loading. Also testing a traditional transactional application is totally different when compared to testing a data warehouse. Typical ETL or data testing paradigm that comes to ones’ mind are:
- Data Transformation – Ensuring, all data has been correctly transformed between source and the target? Which leads to the question, how do I test/automate all my transformations?
- Data Completeness – Verifying all the data has been loaded from the Source to the Target
- Data Validity/Quality – Ensuring the ETL process correctly checks for acceptable values, substitutes default values, corrects and reports erroneous data.
- Regression Testing – Verifying/ensuring that existing functionality remains intact with new code releases.
Even before the entry of Big Data and NoSQL, data volumes existed in Terabytes or Petabytes, the challenge was more around harvesting, processing and deriving insights. In the area of ETL testing, with the addition of Big Data/Hadoop, the question being asked is, “How do we plan and execute testing of data warehouse, with Hadoop being as one of the source or target in the ETL pipeline?”
Started researching on it, came across interesting product that has been in ETL testing space for some time, and their framework can be leveraged to do Big Data Testing. The product is called QuerySurge and is developed by RTTS (Real Time Technology Solutions) Inc. company. QuerySurge is Web 2.0 test tool built to automate and ensure the quality of your data. It provides solutions for Data Warehouse ETL testing, Migration from database/files to another database, Database upgrades, Big Data testing, and Data Interface testing.
Architecture
The architecture of QuerySurge supports any JDBC complaint database or Data Warehouse, and built using Web 2.0 technologies. Being web based, users can be located anywhere. It has Application Server, Database server and Agents, that launches the SQL at the Source and Target referred to as “Query Pairs”, pulls the data back into its internal database, does its compare, and shows the results instantly. QuerySurge uses MYSQL as its’ internal data store.
Features
- Design Library
- Query Pair creation (source and target queries)
- Reusable Query Snippets
- Query Pair management
- Scheduling
- Build Test Scenarios (groups of Query Pairs)
- Build and Schedule Test Suites (groups of Test Scenarios)
- Run Time Dashboard
- Real-Time Execution view
- Real-Time results view
- Results Reporting
- Analyze and Drill-down into Test results
Usage
Scenario #1: Testing a Data Warehouse.
Step 1: QuerySurge executes the SQL at the “Source” and the “Target”. It is referred as “Query Pairs” in QuerySurge terminology. The Source and Target database can be of different types in the ETL pipeline, for example, Source can be Oracle and Target can be Sybase or vice-versa or can be any other JDBC complaint databases.
Step 2: Pulls the data back into its database.
Step 3: Does the compare of every single dataset that may contain thousands or millions of records pulled by the “Query Pairs”, and instantly shows the results.
Step 4: Then, it moves to the next leg in the ETL pipeline. This process can be repeated and automated for all the legs in the ETL pipeline.
Scenario #2: Testing a Database Upgrade.
The same steps and process as shown in scenario #1 gets repeated here.
Scenario #3: Testing a Database migration from one database to another.
The same steps and process as shown in scenario #1 gets repeated here.
Scenario #4: Testing Big Data.
RTTS has partnership with Hortonworks. QuerySurge framework can be leveraged to provide automated ETL testing of Hadoop. Since it can connect to any JDBC complaint database, QuerySurge connection point with Hadoop/HDFS can use HQL (Hive Query Language), Impala, or Spark SQL. Impala, Hive, and Spark SQL provide ODBC and JDBC connection(s).
The use case can be as shown below:
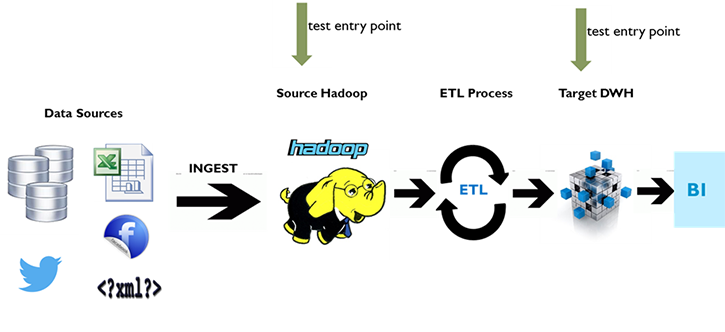
The same steps and process as shown in scenario #1 can be repeated here for the “test entry point” shown above, with Hadoop as the Source and DWH as the Target. QuerySurge can be used to test every leg of the Big Data use case, if needed.
Summary and Potential Areas of Evolution
- QuerySurge currently has hooks/connection point with Hadoop using HQL (Hive Query Language) which can be leveraged to create Query Pairs, and use current framework to test the quality of data with Hadoop. Hadoop can either exist as Source, or Target, of Query Pairs in the ETL pipeline.
- Reusable Query Snippets is a very useful feature in QuerySurge, which can be leveraged by QA automation team to create a “Reusable Code”
- QuerySurge connection points to Hadoop can be through Hive, Impala or Spark SQL, as it can connect to any data store with JDBC connections. Hive, Impala and Spark SQL provides both, ODBC and JDBC connections, and provides SQL skin on top of Hadoop.
- Some of the key potential evolution area that can be foreseen, are as follow:
- Ability to store typical datasets that exists in Hadoop environment, which normally scales between Terabytes to Petabytes? QuerySurge uses MySQL database as its internal store. If it hits the roadblock, have to look at scaling vertically or horizontally, preferably horizontally.
- QuerySurge infrastructure seems to be tightly coupled with design and planning of Query Pairs and data volume, which gets pulled back in its internal MySQL data store. Architecture should be enabled to grow at scale, when Hadoop becomes mainstream for ETL pipeline testing need.
Good References
- QuerySurge – 7 Minute Demo of ETL Testing Tool:https://www.youtube.com/watch?v=ygkmqSijMGg
- ETL Testing – How to achieve 100% Data Validation:https://www.youtube.com/watch?v=rADepO14VHA
- QuerySurge Tutorial – Connection Extensibility, Cloudera and Others:https://www.youtube.com/watch?v=ya_YwUItxKo
- QuerySurge – Data Warehouse Testing Tool from RTTS:https://www.youtube.com/watch?v=Vip568ka_xw
- Testing Big Data – Slide Share:http://www.slideshare.net/RTTS/big-data-testing-automated-etl-testing-of-hadoop?ref
- Testing Big Data – Automated ETL Testing of Hadoop with QuerySurge:https://www.youtube.com/watch?v=MBJEtT-j2fQ


This ETL TEsting article is really very good and easy to understand.